CI/CD
Continuous Integration (CI) and Continuous Delivery (CD) form the backbone of modern software engineering. They automate the testing, validation, and deployment of code, transforming what used to be a months-long manual release cycle into a reliable process that takes minutes or hours.
Why CI/CD?
Section titled “Why CI/CD?”Before CI/CD, software releases were manual, infrequent, and high-risk. Code sat in feature branches for weeks; integration was a painful, multi-day event; and deployments happened after-hours with a team on standby ready to roll back. The feedback loop between writing code and knowing if it worked in production was measured in days or weeks - long enough for bugs to compound and context to evaporate.
CI/CD solves this by collapsing that feedback loop into minutes:
| Benefit | What it means in practice |
|---|---|
| Faster feedback | Automated tests and code reviews give developers immediate signal on whether their change broke anything - before it ever reaches production. |
| Higher reliability | Frequent, smaller releases with automated validation reduce the blast radius of any single change, lowering the risk of downtime. |
| Better collaboration | Shared pipelines, common tooling, and enforced standards reduce conflicts and keep distributed teams aligned. |
| Lower costs | Automated testing catches defects early when they’re cheap to fix. Cloud-native infrastructure and containers eliminate idle capacity. |
Pipelines and infrastructure are the two structural components that make this possible - the pipeline automates the work; the infrastructure provides the environment to run it in.
The Evolution of CI/CD
Section titled “The Evolution of CI/CD”CI/CD has undergone a fundamental shift over the past decade - not just in tooling, but in how the discipline is conceptualized and applied. Four key transitions define this evolution:
| Then | Now |
|---|---|
| Reference architectures - abstract, untested guidelines | Design patterns - proven, reusable solutions from real implementations |
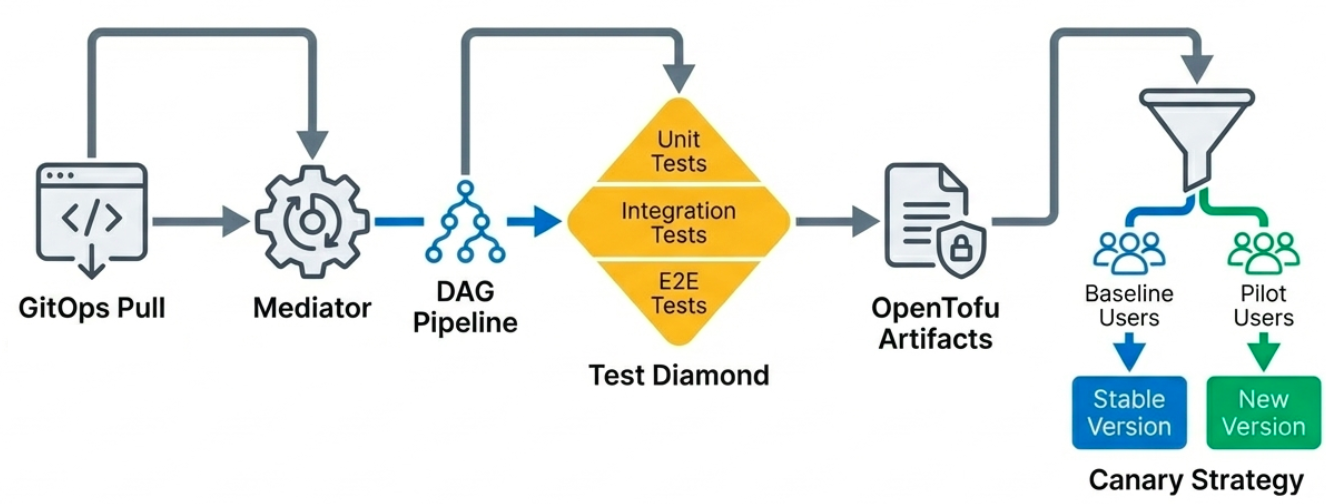
| Push model - a commit triggers the pipeline, which pushes changes to production | Pull model (GitOps) - a controller continuously reconciles live state with the desired state in Git |
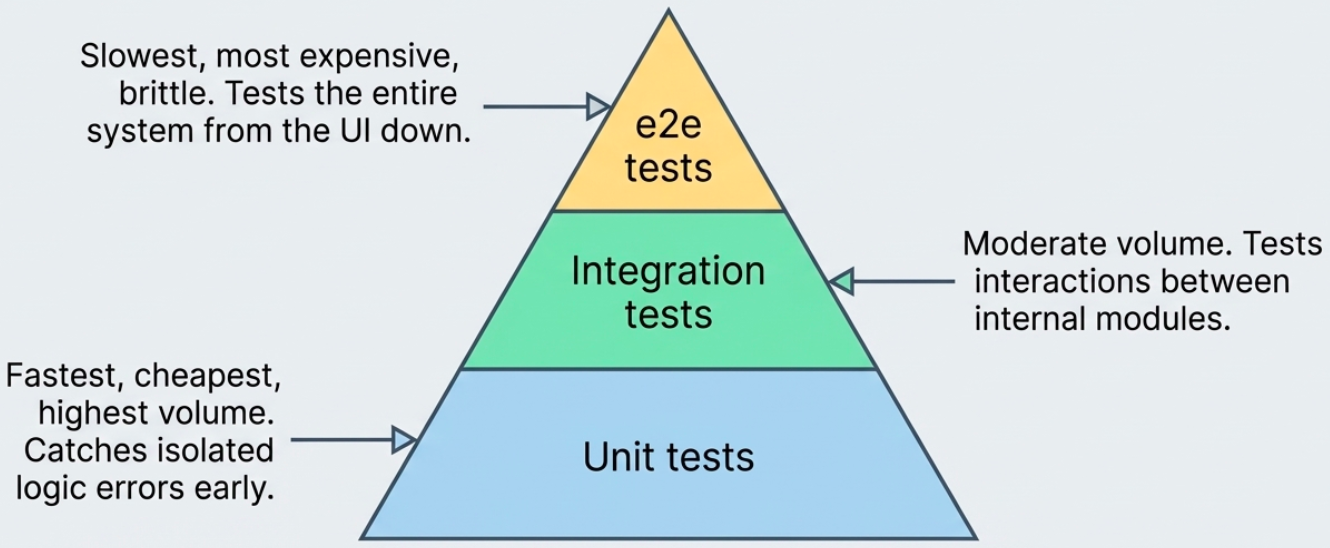
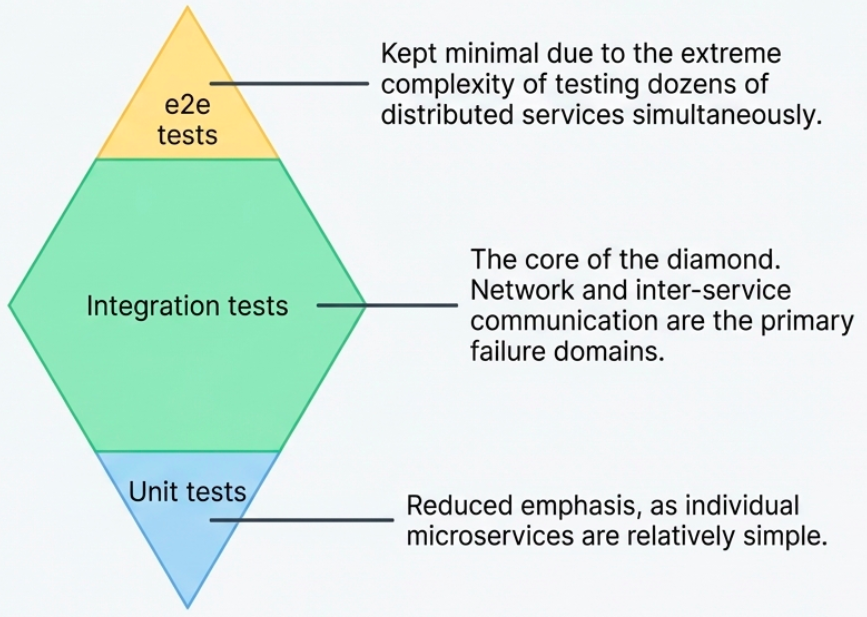
| Test Pyramid - unit-test heavy, designed for monoliths | Test Diamond - integration-test heavy, designed for microservices |
| App code only - CI/CD automated the build and deploy of source code | Infrastructure as Code (IaC) - CI/CD now manages cloud infrastructure with the same rigor |
Key Components of CI/CD
Section titled “Key Components of CI/CD”-
Pipelines: The backbone of any CI/CD setup - a sequence of automated stages that take your code from commit to deployment. Each stage (build, test, package, deploy) has a clear job: catch problems early, fail fast, and keep humans out of repetitive work. Pipelines aren’t one-size-fits-all; they adapt to whatever they’re moving - source code, container images, Helm charts, or config bundles.
-
Infrastructure: Everything the pipeline runs on - servers, networks, storage, databases, containers, and cloud services. This breaks down into two layers:
- Provisioning tools (Terraform, Ansible, Chef, Puppet) automate the creation and management of these resources so environments are reproducible and consistent.
- Observability tools (Prometheus, Grafana, Nagios, Datadog) monitor infrastructure health, surface pipeline bottlenecks, and close the feedback loop between deployment and performance.
Poor infrastructure choices - undersized runners, no caching, flaky test environments - are usually the first thing that makes pipelines slow and unreliable.
The CI/CD Pipeline
Section titled “The CI/CD Pipeline”A CI/CD pipeline is an automated workflow that bridges the gap between writing code and delivering it to users.
- Continuous Integration (CI): The practice of frequently merging code changes into a central repository. Each merge triggers an automated build and test suite to validate the integration.
- Continuous Delivery (CD): The automated process of pushing the validated build to a target environment (staging or production) so users can access it.
The connection point between CI and CD is the artifact - the packaged, tested output (a Docker image, JAR file, or binary) that travels from the integration phase into delivery. Without CI/CD, developers would manually build, test, scan, and deploy code for every change - a slow, error-prone process that scales poorly.
Every CI/CD pipeline is built around the same core build cycle:
| Phase | What happens |
|---|---|
| Source control | A push or PR triggers the pipeline via a VCS hook (Git being the default) |
| Initialization | The build system prepares the environment, installs dependencies, and sets up the workspace. |
| Compilation | Source code is converted into executable code (or a distributable format for interpreted languages). |
| Testing | Automated tests run to validate correctness - unit, integration, and end-to-end checks. |
| Packaging | The tested code is assembled into a deployable artifact: a Docker image, JAR, binary, or archive. |
| Review / Deploy | The artifact is inspected (quality gates, security scans) and promoted to a target environment. |
| Monitor & feedback | Runtime metrics and alerts close the loop back to the team |
Pipeline Types
Section titled “Pipeline Types”Pipelines come in several flavors, each suited to different workflow needs:
-
Basic pipelines: The simplest form - stages run sequentially, and all jobs within a stage run concurrently. Once every job in a stage completes, the pipeline moves to the next. A typical example: build → test → deploy. Good starting point, but limited flexibility for complex dependency graphs.
-
DAG pipelines: Instead of rigid stage ordering, a Directed Acyclic Graph (DAG) pipeline runs jobs based on their dependencies. Jobs with no dependency on each other run in parallel; those that depend on prior results wait. This makes DAG pipelines significantly faster for complex workflows - linting, unit tests, integration tests, and coverage checks can all run optimally without unnecessary serialization.
-
Merge request pipelines: Triggered only on merge requests, not every commit. Useful for running heavier checks (test suites, static analysis) specifically on proposed changes before they touch the main branch - without burning CI minutes on every push to a feature branch.
-
Merged results pipelines: A step further - these pipelines test the outcome of the merge, not just the source branch. They simulate what the codebase looks like after the merge and run checks against that, catching conflicts or regressions before they land.
-
Merge trains: Built on top of merged results pipelines, merge trains queue merge requests sequentially and test each one against the latest state of the target branch. Only one MR merges at a time, which eliminates the “works on my branch” class of integration failures at the cost of some throughput.
The right pipeline type depends on your team’s scale and tolerance for CI complexity. Most teams start with basic pipelines and graduate to DAGs or merge trains as their codebase and team size grow.
Standard Pipeline Stages
Section titled “Standard Pipeline Stages”While pipelines vary based on the stack and target environment, a robust pipeline typically executes these stages in sequence:
| Stage | Purpose | Example Tools |
|---|---|---|
| Unit Testing | Tests specific functions or blocks of code in isolation (e.g., verifying add(2, 3) returns 5). | JUnit, PyTest, Jest |
| Static Code Analysis | Ensures code is correct, properly formatted, and free of anti-patterns (e.g., unused variables). | SonarQube, ESLint, Checkstyle |
| Vulnerability Scanning | Scans dependencies and application code for known security vulnerabilities (CVEs). | Snyk, Trivy, Dependabot |
| Functional / End-to-End | Validates that new changes don’t break existing user flows or system integrations. | Selenium, Cypress, Playwright |
| Reporting / Artifacts | Stores test coverage reports, build logs, and the final compiled artifact (e.g., a Docker image or JAR). | Nexus, Artifactory, JaCoCo |
| Deployment | The final stage - the application is pushed to a live environment for users or QA. | ArgoCD, AWS CodeDeploy |
The Role of Version Control
Section titled “The Role of Version Control”The pipeline is entirely driven by the Version Control System (VCS) - GitHub, GitLab, or Bitbucket.
Developers build features locally and push commits to the VCS. Once pushed (or when a Pull Request is opened), the VCS emits an event that triggers the CI/CD pipeline automatically.
Traditional CI/CD: Jenkins
Section titled “Traditional CI/CD: Jenkins”Jenkins is the classic CI/CD orchestrator. It acts as the command center, integrating with external tools (Maven, SonarQube, Kubernetes) to execute pipeline stages.
A traditional Jenkins pipeline promotes an application progressively through environments:
- Dev: A minimal setup (e.g., a single EC2 instance) for initial QA and integration testing.
- Staging: A scaled-up replica of production to validate behavior under realistic conditions.
- Production: The live environment serving customer traffic.
The Scaling Problem with Jenkins
Section titled “The Scaling Problem with Jenkins”Jenkins relies on static VMs acting as persistent worker nodes - the “pets” of infrastructure.
Modern CI/CD: Ephemeral & Containerized
Section titled “Modern CI/CD: Ephemeral & Containerized”Modern platforms - GitHub Actions, GitLab CI/CD, CircleCI - solve the wasted compute problem by shifting to an ephemeral, containerized model.
When a repository event fires, the platform spins up a temporary Docker container (or Kubernetes pod) to run the pipeline. Once the job completes, the container is destroyed.
- Zero Wasted Compute: You only pay for the minutes your pipeline runs. No commits = zero compute consumed.
- Massive Scalability: The provider handles the infrastructure. Hundreds of concurrent jobs run without manual provisioning.
- Native Events: GitHub Actions and GitLab CI/CD are built into the VCS - they understand PRs, tags, and branch rules without webhook configuration.
Orchestration Tools
Section titled “Orchestration Tools”Orchestration is what coordinates when and how each stage runs:
| Tool | Best For | Notes |
|---|---|---|
| Jenkins | Self-hosted, customizable setups | Mature ecosystem, extensive plugin support; operational overhead is real |
| GitLab CI/CD | Teams already on GitLab | Pipeline config lives in the repo; tight VCS integration out of the box |
| GitHub Actions | GitHub-native workflows | Easy to set up; large marketplace of community actions |
| Travis CI | Open source projects | GitHub-integrated, simple config; less common in enterprise now |
| Azure DevOps | Microsoft/enterprise environments | Full lifecycle tooling; deep Azure integration |
| Argo CD | Kubernetes + GitOps | Git as source of truth for cluster state; pairs well with Helm and Kustomize |
| Tekton | Kubernetes-native CI/CD | CRD-based pipeline definitions; default in Red Hat OpenShift |
Push vs. Pull: The Two Delivery Models
Section titled “Push vs. Pull: The Two Delivery Models”There are two fundamental models for how changes move from Git to a running system:
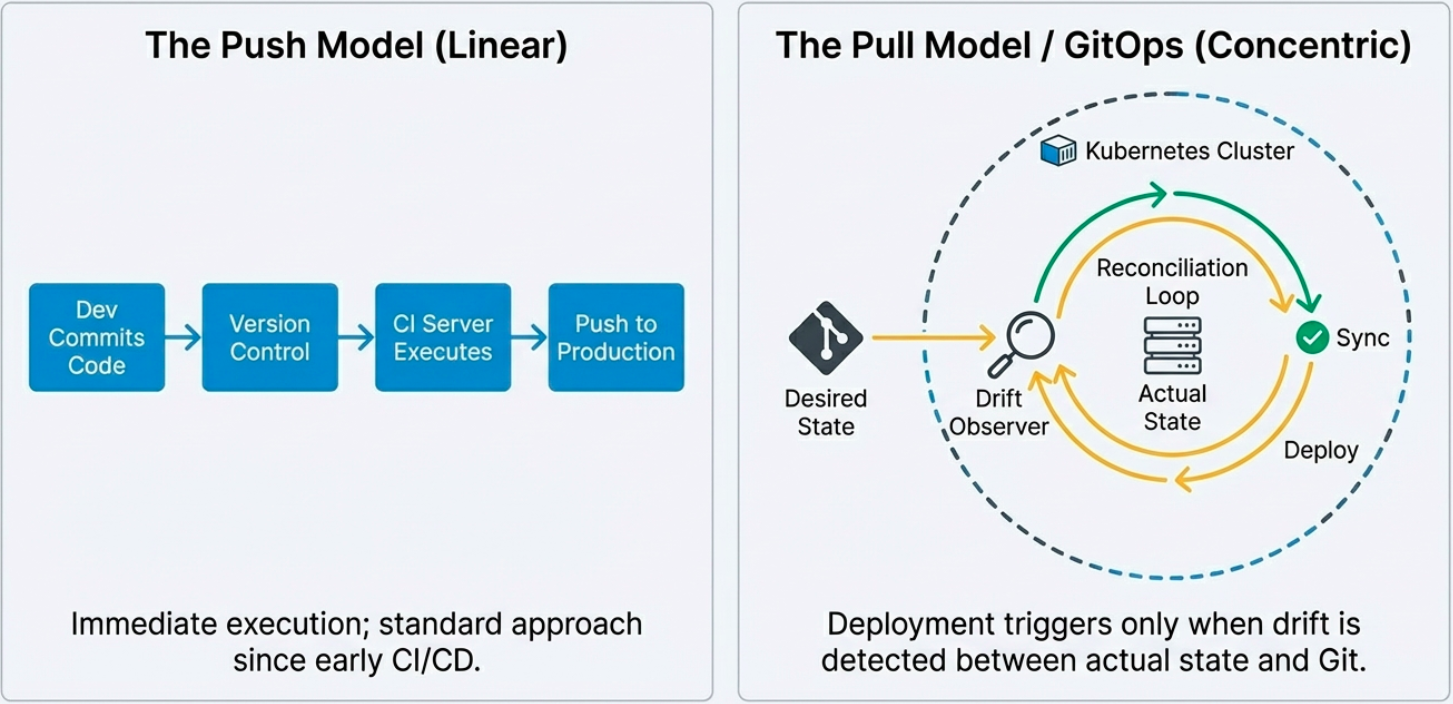
- Push model (Traditional CI/CD): A code commit triggers the pipeline, which pushes the artifact directly into the target environment. Simple to reason about, but the pipeline needs credentials to access production systems.
- Pull model (GitOps): A controller inside the cluster constantly compares the live state against the desired state declared in Git. When it detects a difference, it pulls and reconciles. No external credentials are needed in the pipeline.
GitOps is the modern evolution of this pull model, specifically for Kubernetes environments. It is more secure (credentials stay inside the cluster) and provides automatic drift detection. Tools: ArgoCD, Flux.
Design Patterns in CI/CD
Section titled “Design Patterns in CI/CD”CI/CD isn’t just tooling - it’s an engineering discipline. The same software design patterns that structure application code also apply to how pipelines and delivery infrastructure are organized.
Design patterns are general, reusable solutions to recurring problems. They promote reusability, provide a common vocabulary, ensure maintainability, and produce adaptable systems. The three classical categories map directly into CI/CD contexts:
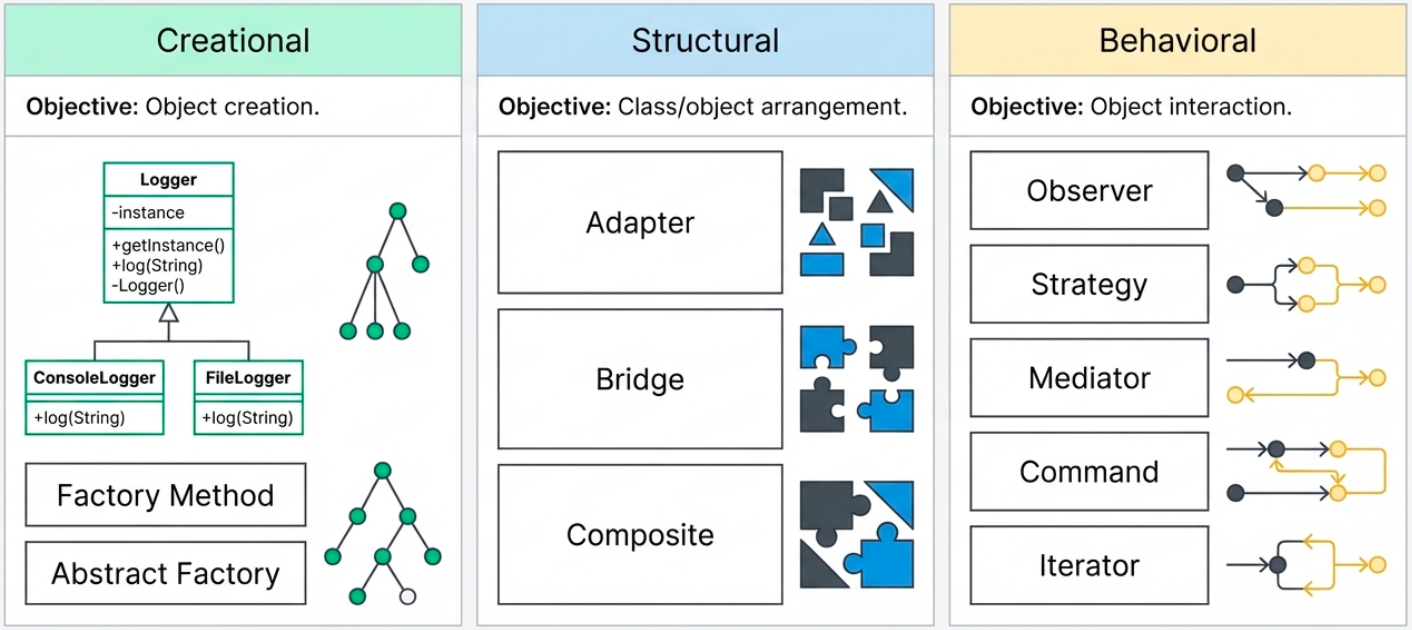
| Category | What it does | CI/CD Examples |
|---|---|---|
| Creational | Structured and efficient creation of pipeline objects | Singleton pipeline config, Factory for environment-specific pipelines |
| Structural | Simplifies how pipeline components are arranged and composed | Adapter for integrating legacy tools, Composite for modular job groups |
| Behavioral | Focuses on communication and interaction between stages | Observer for pipeline notifications, Strategy for swappable deployment algorithms |
The Factory Method in Practice
Section titled “The Factory Method in Practice”When building a CI/CD system, the Factory Method pattern can be applied to create different types of deployment pipelines - each with specific steps, tools, and configurations - without changing the pipeline orchestration logic.
The pattern works by defining an abstract PipelineCreator with a createPipeline() factory method. Concrete subclasses (DevelopmentPipelineCreator, StagingPipelineCreator, ProductionPipelineCreator) each implement their own version, returning the appropriate DeploymentPipeline instance (development, staging, or production) with the correct tooling and deployment targets pre-configured.
The result: your orchestration layer stays consistent while the environment-specific details are encapsulated in each concrete creator. Swapping out a deployment strategy for a single environment requires changing one class, not the whole pipeline definition.
The scope of CI/CD has also expanded beyond application code to include Infrastructure as Code (IaC). Modern pipelines manage cloud resources with the same rigor - using state files, pull request gates, cost analysis, golden images, and drift detection pipelines. See Pipeline as Code for the full breakdown.
Testing Strategies
Section titled “Testing Strategies”The right testing strategy depends on your application architecture:
-
Test Pyramid - best for monolithic applications. Emphasizes a large base of fast, cheap unit tests, fewer integration tests, and a small number of end-to-end tests at the top.
-
Test Diamond - best for microservices and distributed systems. Shifts emphasis to integration tests, because the communication layer between services is where failures actually occur. Unit tests remain but carry less weight individually.
Deployment Strategies
Section titled “Deployment Strategies”How new code reaches users is one of the most consequential decisions in a CI/CD system. The three foundational strategies:
-
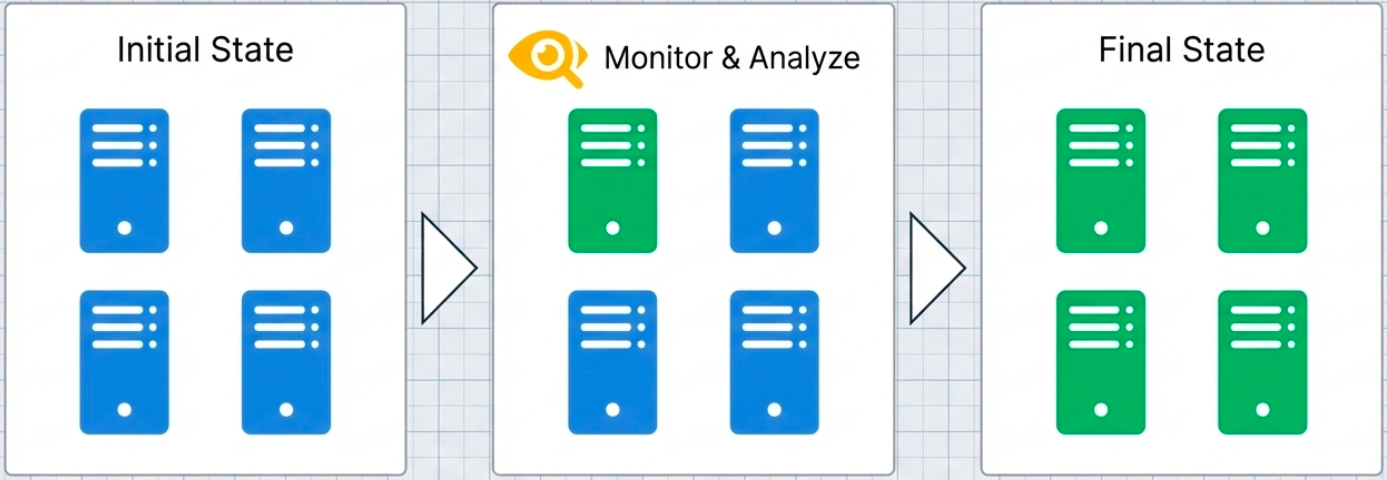
Rolling: Gradually replaces old instances with new ones. No duplicate infrastructure required; risk is contained to the fraction of traffic hitting the new version at any moment.
-
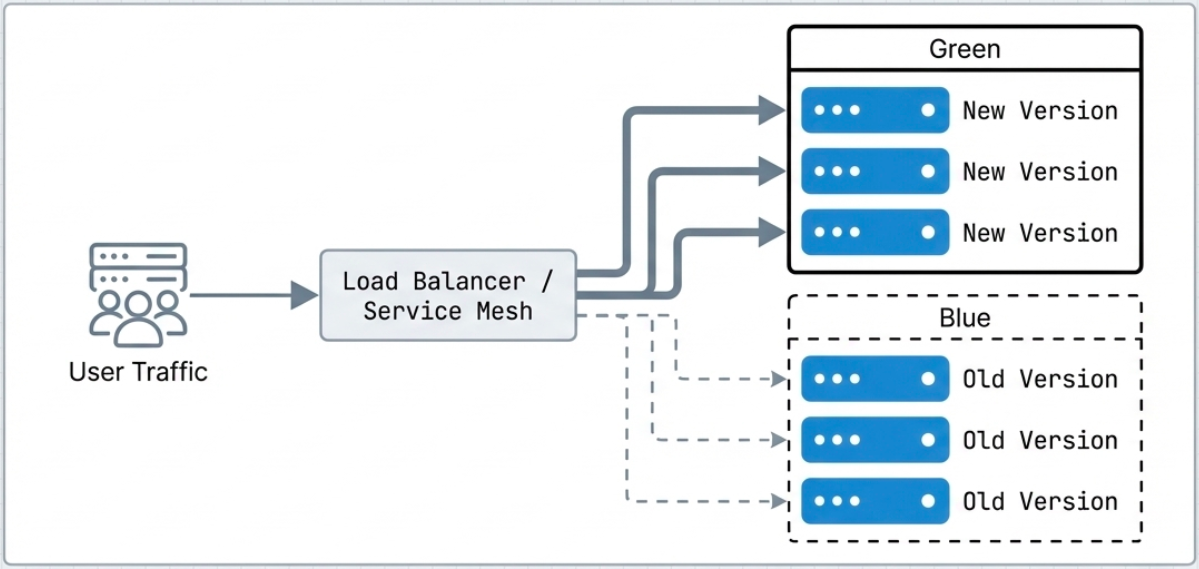
Blue-Green (Red-Black): Maintains two identical production environments. The new version (Green) is deployed and fully tested before a load balancer atomically flips all traffic from Blue to Green. Zero downtime; instant rollback by flipping back.
-
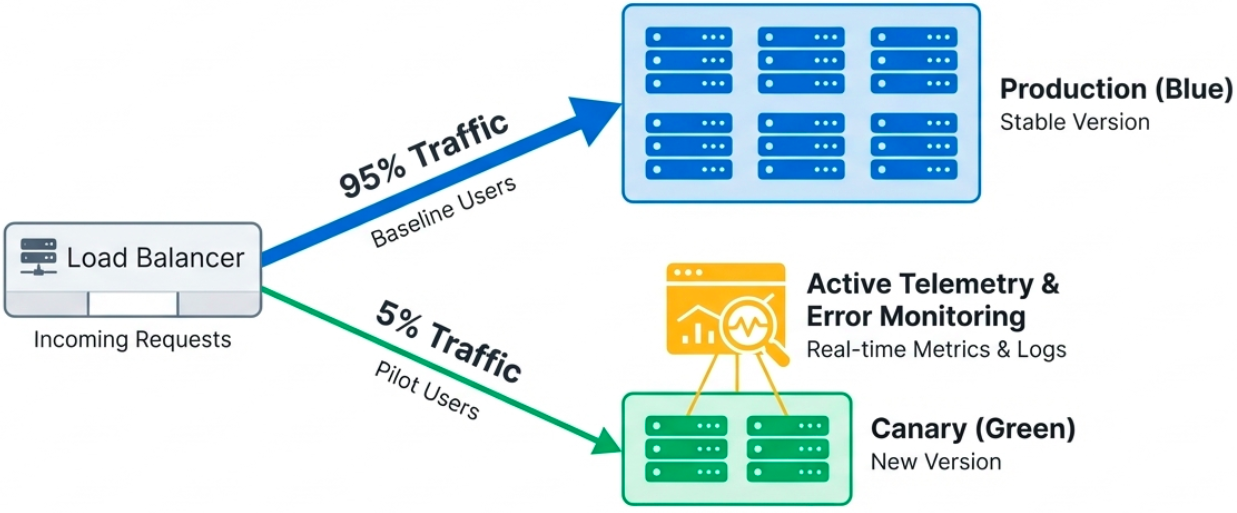
Canary: Releases the new version to a small slice of real users first. Metrics are observed before incrementally routing more traffic until 100% is on the new version - or rolling back if signals degrade.
See Deployment Strategies for the full breakdown, including Feature Toggles, A/B Testing, and Dark Launches.
CI/CD as a Software Factory
Section titled “CI/CD as a Software Factory”CI/CD is not a set of tools. It is a cultural and operational discipline that applies the rigor of software design patterns to the infrastructure that delivers software. When fully realized, the pipeline becomes a Software Factory - raw code goes in, tested and deployed software comes out, reliably and repeatedly.
Best Practices
Section titled “Best Practices”Teams that implement CI/CD successfully share a common set of practices. These aren’t optional optimizations - they are the conditions that make the pipeline trustworthy:
| Practice | What it looks like | Why it matters |
|---|---|---|
| Branching strategy | Adopt trunk-based development or a documented GitFlow variant | Keeps main always deployable; reduces merge conflict risk |
| Automated testing on every commit | Unit tests + integration tests run on each push, no exceptions | The testing gap is where bugs survive to production |
| Code quality analysis | Run SonarQube, CodeClimate, or Codacy as a pipeline gate | Catches complexity, duplication, and security issues automatically |
| Peer code review | Every PR requires at least one reviewer before merge | Catches issues early; propagates knowledge across the team |
| Infrastructure as Code | Provision all environments with Terraform, Ansible, or Pulumi | Eliminates environment drift; enables reproducible builds |
| Monitoring and observability | Deploy Prometheus, Grafana, or Datadog alongside every release | Closes the feedback loop between deployment and production health |
| Communication and feedback | Post pipeline results to Slack/Teams; track work in Jira or Linear | Keeps stakeholders aligned and surfacing failures fast |
Common Challenges
Section titled “Common Challenges”CI/CD adoption is consistently difficult. Most organizations encounter the same set of obstacles:
| Challenge | Root cause | Recommended approach |
|---|---|---|
| Integration complexity | Applying CI/CD to legacy or large-scale projects involves untangling years of manual processes | Start with a subset of the codebase; prove value incrementally before expanding |
| Security and compliance gaps | Automated pipelines move fast and can ship vulnerabilities just as fast as features | Integrate SAST, DAST, and dependency scanning as non-negotiable pipeline stages |
| Operational hurdles | Managing runners, caching, artifact storage, and scaling pipelines is real infrastructure work | Treat the pipeline as a product; assign ownership and invest in its health |
| Knowledge gaps | New tools, new paradigms, and cultural change all at once overwhelms teams | Invest in training, start small, and favor simplicity over sophistication initially |